Getting Started with Edge AI: Running Neural Networks on Microcontrollers
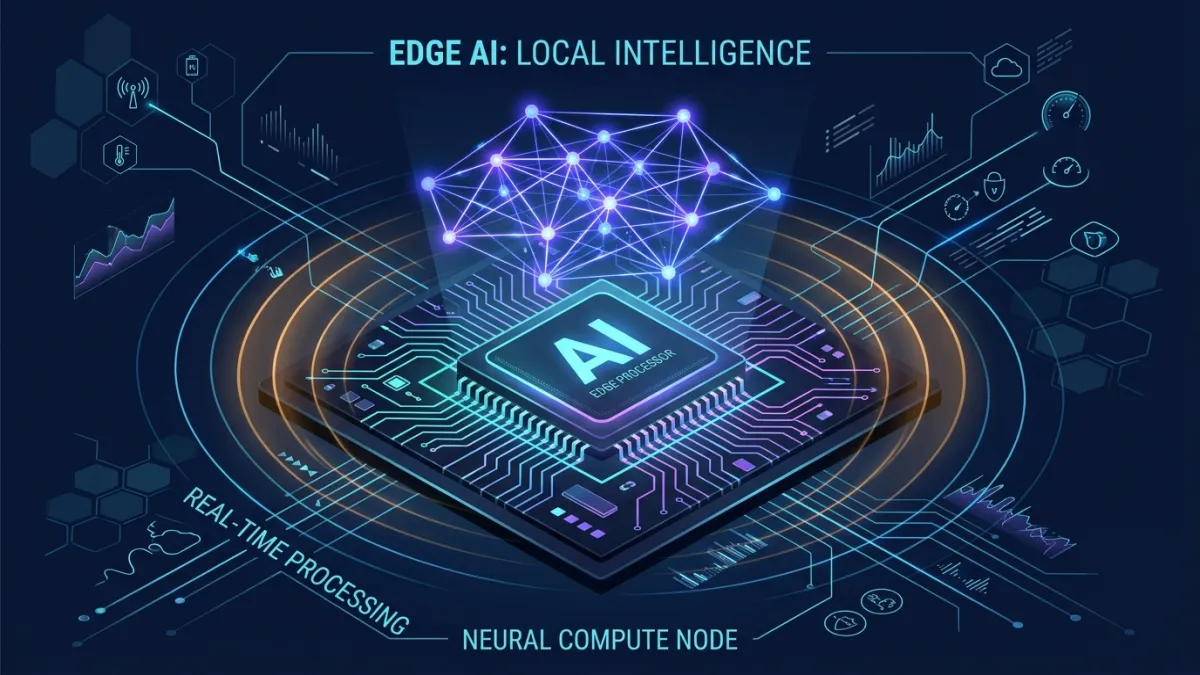
- Edge AI (TinyML) runs compact neural networks directly on low-power microcontrollers rather than remote cloud servers.
- Very low latency and high privacy: Local inference eliminates network round-trips and keeps raw audio, visual, and vibration data on the device.
- Quantization (FP32 to INT8) reduces model memory footprints by 75% with usually a small accuracy loss, making neural execution practical inside kilobytes of SRAM.
When people think of artificial intelligence, they often picture massive data centers filled with liquid-cooled graphics processors consuming megawatts of electricity. Yet an equally transformative engineering movement is happening at the opposite end of the computing spectrum: Edge AI and TinyML.
Instead of streaming raw sensor readings over Wi-Fi or cellular networks to a distant server, Edge AI executes trained machine learning models directly on the physical hardware where the data originates. Whether the host device is a microcontroller bolted to an industrial pump, a wearable health monitor, or the wrist controller of a humanoid robot, local intelligence enables machines to interpret the physical world in real time.
What is Edge AI and How Does It Differ from Cloud AI?
In a traditional cloud AI architecture, a device acts only as a data collector. A microphone records audio, compresses the stream, transmits it across a local router to an internet backbone, waits for a datacenter GPU to run inference, and receives a JSON response. That pipeline works well for open-ended chat assistants, but it creates severe bottlenecks for Physical AI and embedded automation.
In contrast, Edge AI embeds the mathematical weights of a neural network straight into the flash memory of a microcontroller or edge neural processing unit (NPU). Frameworks such as LiteRT for Microcontrollers (formerly TensorFlow Lite Micro) execute inference without requiring an operating system, dynamic memory allocation, or internet connectivity.
Four Engineering Reasons to Run AI on the Edge
- Very low latency: Inference happens locally in milliseconds without waiting for round-trip network hops over Wi-Fi, 4G, or 5G. When a robotic gripper detects part slippage, a 5-millisecond local reflex loop prevents a drop that a 250-millisecond cloud round-trip could not catch.
- Bandwidth and Privacy Protection: Streaming continuous high-rate sensor feeds—such as 16 kHz audio, 1 kHz three-axis accelerometer vibration, or camera frames—consumes wireless bandwidth and battery power. Processing data locally means sensitive audio and visual feeds never leave the physical device.
- Offline Reliability: Agricultural drones, underground mining rovers, and factory safety interlocks must function deterministically even when wireless signals drop or routers fail.
- Milliwatt Power Envelopes: A microcontroller running TinyML can remain in deep sleep drawing microamps, wake via a hardware interrupt when a sensor threshold is crossed, evaluate a neural network in a few milliseconds, and return to sleep.
How Do Neural Networks Fit Inside a Microcontroller?
A standard microcontroller typically provides between 256 kilobytes and 512 kilobytes of static RAM (SRAM) and a few megabytes of flash storage. By comparison, even a modest computer vision model on a desktop workstation can occupy hundreds of megabytes. Fitting useful pattern recognition into microcontroller memory requires three systematic compression steps during training and deployment:
- Quantization: Converting 32-bit floating-point weights (FP32) and activations into 8-bit integers (INT8), slashing memory consumption by 75% with usually a small accuracy loss. As documented in the TensorFlow Model Optimization Quantization Guide, quantization-aware training simulates lower-precision rounding during backpropagation so the network adapts before deployment.
- Structured Pruning: Identifying neural connections or convolutional filters whose weights remain near zero and removing them altogether, reducing both flash footprint and the number of multiply-accumulate (MAC) operations per inference cycle.
- Knowledge Distillation: Training a compact “student” network with only a few dozen kilobytes of parameters to match the probability distributions of a much larger “teacher” network trained on a workstation.
Inside the Real-Time Edge Inference Loop
A common misconception is that TinyML feeds raw, noisy sensor samples directly into a deep neural network. On resource-constrained chips, digital signal processing (DSP) and neural inference work together. First, a direct memory access (DMA) controller copies raw samples from an I2S microphone or SPI accelerometer into a circular buffer without waking the main CPU core on every sample.
Second, a deterministic preprocessing step converts that time-series window into a compact feature map—such as a Mel-frequency cepstral coefficient (MFCC) spectrogram for audio wake-words, or fast Fourier transform (FFT) frequency bins for bearing vibration monitoring. Finally, the static LiteRT Micro interpreter evaluates the quantized convolutional or recurrent layers inside a pre-allocated block of RAM called the tensor arena.
Practical Hardware Platforms for Beginners and Engineers
Selecting hardware for an embedded machine learning project depends on the sensor modality—audio and inertial signals require far less compute than camera vision. Three widely documented microcontroller platforms cover the majority of entry-level and industrial prototyping needs:
ESP32-S3
According to the Espressif ESP32-S3 Hardware Reference, this dual-core 240 MHz Xtensa LX7 microcontroller includes vector instructions (SIMD) that accelerate 8-bit and 16-bit neural matrix multiplication alongside integrated Wi-Fi and Bluetooth LE.
Arduino Nano 33 BLE Sense
Built around a 64 MHz Arm Cortex-M4F processor with hardware floating-point support, the Arduino Nano 33 BLE Sense integrates an onboard digital microphone, 9-axis IMU, and environmental sensors on a single stamp-sized PCB, eliminating breadboard wiring errors.
Arm Cortex-M55 + Ethos-U55
For higher-throughput vision and multi-sensor fusion in robotics, modern microcontrollers pair an Arm Cortex-M55 core with a dedicated microNPU capable of hundreds of millions of operations per second at milliwatt power levels.
Engineering Constraints and Memory Budgeting
When deploying a quantized model to a microcontroller, engineers must account for both non-volatile flash storage and volatile SRAM. Flash stores the immutable weight tensors and operator code, whereas SRAM must hold the peak intermediate activation buffers of the largest layer during forward propagation. Because embedded C++ runtimes avoid heap fragmentation by disabling malloc() and free() during inference, developers pre-allocate a contiguous byte array for the tensor arena and profile its exact high-water mark before flashing production firmware.
Real-World Robotics Example: Tactile and Edge Sensing
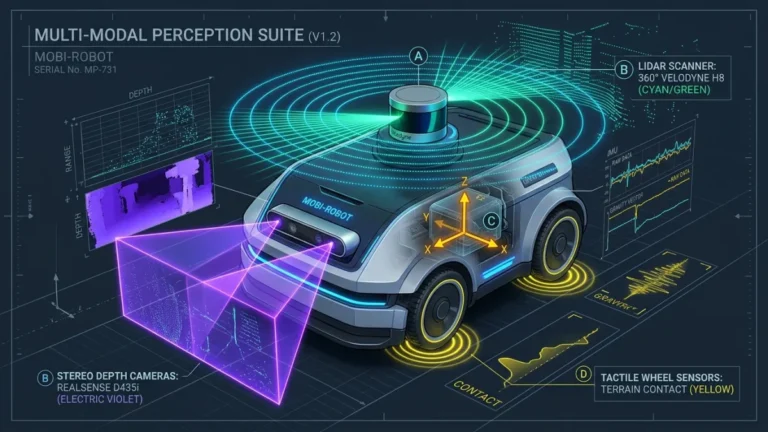
In advanced robotic manipulation, edge microcontrollers embedded directly inside a robot’s fingertips process high-frequency pressure and slip signals before sending summarized state updates to the central computer. For a broader look at how cameras, inertial units, and force transducers work together, explore our guide on the sensors a robot needs.
This IEEE Spectrum video demonstrates how localized fingertip tactile sensors capture high-resolution contact forces at the edge to enable delicate robotic grasping:
From my own experience
[ADD MY EXPERIENCE: Describe a microcontroller board you tested for TinyML inference, the sensor you connected, and what latency or memory trade-offs you observed.]
Sources
- LiteRT for Microcontrollers Overview (Google Edge Developers) — Official technical documentation for running TensorFlow / LiteRT models on kilobyte-scale microcontrollers.
- Quantization Aware Training Guide (TensorFlow Model Optimization) — Primary technical guide on FP32-to-INT8 quantization mechanics and accuracy trade-offs.
- ESP32-S3 Hardware Reference (Espressif Systems) — Manufacturer hardware documentation for the ESP32-S3 dual-core MCU with vector neural extensions.
- Arduino Nano 33 BLE Sense Official Documentation — Official hardware specifications and onboard sensor reference for TinyML prototyping.
Last updated: November 3, 2026