How Robots Learn: Reinforcement Learning vs Imitation Learning
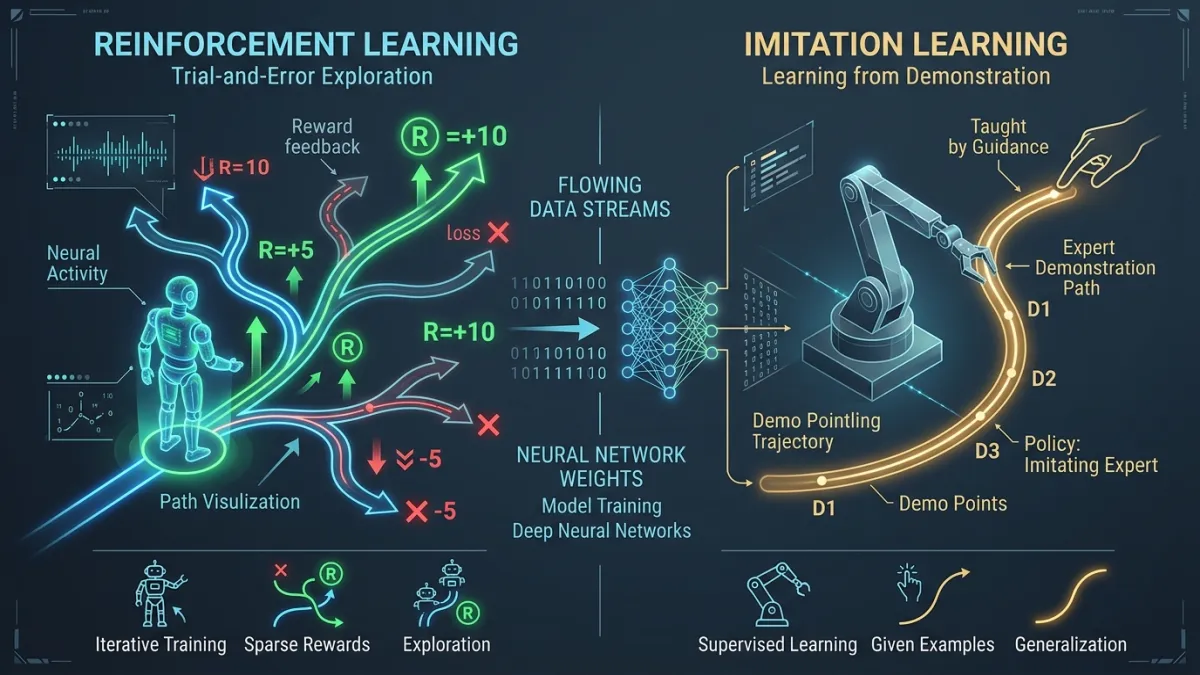
- Reinforcement Learning (RL) discovers control policies through trial-and-error reward optimization—ideal for locomotion and whole-body balance in fast simulators.
- Imitation Learning (Behavior Cloning) trains policies directly from human teleoperation demonstrations—ideal for dexterous bimanual manipulation.
- Modern hybrid pipelines combine imitation pre-training with reinforcement fine-tuning to achieve both sample efficiency and out-of-distribution robustness.
How do you teach a robot to thread a cable, fold a towel, or walk across loose gravel? For decades, robotics engineers wrote explicit conditional rules and inverse kinematics equations for every motion. Today, Physical AI relies on two foundational machine learning paradigms to acquire motor skills: Reinforcement Learning (RL) and Imitation Learning (IL).
Although both paradigms output neural network policies that map sensor observations to motor commands, they solve the learning problem from opposite directions. Understanding when to use reinforcement learning, when to use imitation learning, and how to combine them is one of the most practical architectural decisions in modern robotics.
1. Reinforcement Learning: Mastering Skills Through Trial and Reward
In reinforcement learning, nobody shows the robot how to perform the task. Instead, the engineer defines a mathematical framework called a Markov Decision Process (MDP) consisting of an observation space (such as joint angles, angular velocities, and IMU readings), an action space (target joint torques or positions), and a scalar reward function.
As detailed in the OpenAI Spinning Up Introduction to Reinforcement Learning, the agent interacts with its environment in discrete time steps. At each step, the policy outputs an action, the physics engine advances the world state, and the reward function scores the outcome—for example, awarding $+1.0$ for forward torso velocity while subtracting $-0.05$ for excessive motor torque or joint jerk.
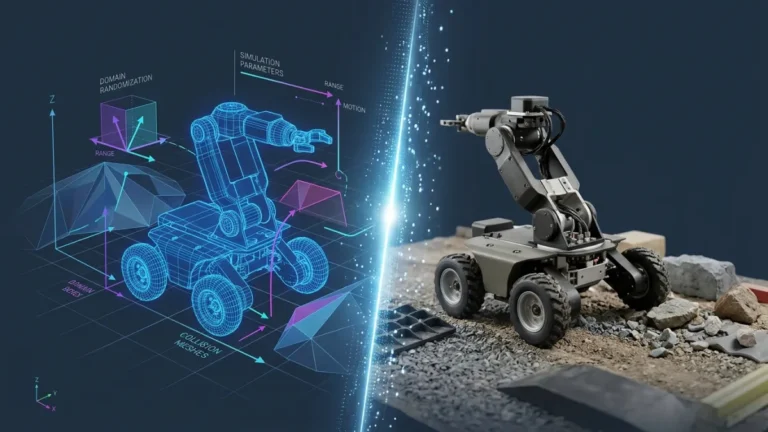
Policy-gradient algorithms such as Proximal Policy Optimization (PPO), introduced in Schulman et al. (arXiv:1707.06347), iteratively adjust the neural network weights so high-reward trajectories become more probable. Because PPO clips policy updates within a safe trust region, it has become the standard workhorse for training quadrupeds and humanoid robots inside massively parallel GPU simulators.
Strengths and Limitations of Reinforcement Learning
- Superhuman Reflex Discovery: Because an RL agent explores millions of perturbations, it can discover recovery steps and whole-body balance maneuvers that a human teleoperator could never react fast enough to demonstrate.
- The Reward Engineering Trap: Designing a dense, well-behaved reward function for multi-stage manipulation (such as unzipping a bag) is notoriously difficult. Poorly shaped rewards lead to “reward hacking,” where the robot exploits simulator quirks without solving the real task.
- Hardware Wear During Exploration: Random trial-and-error exploration cannot be run from scratch on an expensive physical robot arm without risking mechanical collisions, making simulation mandatory.
2. Imitation Learning: Learning Directly from Expert Demonstrations
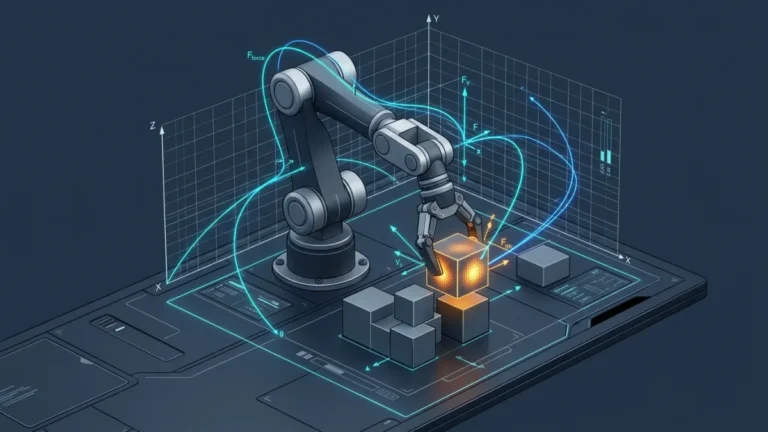
Rather than waiting for a robot to stumble upon the right sequence of motions by chance, Imitation Learning (most commonly implemented as Behavior Cloning) treats robot control as a supervised learning problem. A human operator teleoperates the robot—using leader-follower arms, virtual reality controllers, or motion-capture gloves—to record a dataset of synchronized sensor observations and expert actions.
Historically, naive behavior cloning suffered from a fatal flaw known as compounding covariate shift. If a policy predicts only a single 20-millisecond action step at a time, tiny prediction errors accumulate rapidly, pushing the robot into unfamiliar states that never appeared in the human training demonstrations.
Modern imitation learning overcomes this drift through Action Chunking and generative policies. In the landmark paper Learning Fine-Grained Bimanual Manipulation with Low-Cost Hardware (ALOHA / ACT, arXiv:2303.04137), researchers introduced Action Chunking with Transformers (ACT). Instead of predicting one motor step, the transformer predicts a coherent sequence (chunk) of $k$ future actions at once and blends overlapping predictions temporally, enabling fine-grained tasks like slotting batteries or opening plastic condiment cups from just 50 human demonstrations.
Head-to-Head Comparison: RL vs. Imitation Learning
| Engineering Dimension | Reinforcement Learning (RL) | Imitation Learning (IL) |
|---|---|---|
| Primary Data Source | Billions of synthetic steps in GPU physics simulators | 50 to 1,000+ human teleoperation trajectories on real or simulated robots |
| Best-Fit Applications | Bipedal/quadruped locomotion, agile balance, contact-rich gait recovery | Dexterous bimanual manipulation, tool use, deformable object handling |
| Main Engineering Bottleneck | Reward function design and bridging the sim-to-real gap | Collecting high-quality human teleoperation data and handling out-of-distribution states |
| Can Exceed Human Skill? | Yes—optimizes reaction speed and torque efficiency beyond human reflexes | Rarely on its own—bounded by the quality and speed of the human demonstrator |
The Future: Combining Imitation and Reinforcement Learning
In contemporary robotics labs, reinforcement learning and imitation learning are no longer viewed as mutually exclusive competitors. State-of-the-art pipelines initialize a policy network using behavior cloning on human demonstrations (or motion-capture clips) so the robot immediately understands the coarse structure of the skill. Next, engineers fine-tune that policy with reinforcement learning so the robot practices recovering from slips, sensor noise, and object perturbations.
This official Google DeepMind video illustrates how modern embodied AI combines multimodal demonstrations and trial refinement to master physical motor skills:
From my own experience
[ADD MY EXPERIENCE: Describe an experiment where you trained an RL policy in simulation or collected teleoperation demonstrations for behavior cloning.]
Sources
- OpenAI Spinning Up: Introduction to Reinforcement Learning — Foundational mathematical documentation covering Markov Decision Processes, policy gradients, and value functions.
- Proximal Policy Optimization Algorithms (arXiv:1707.06347) — Primary research paper introducing PPO, the standard reinforcement learning algorithm for continuous robot control.
- Learning Fine-Grained Bimanual Manipulation with Low-Cost Hardware (arXiv:2303.04137) — Primary research paper introducing Action Chunking with Transformers (ACT) and the ALOHA teleoperation system.
Last updated: November 3, 2026